 Mindset docs
Optimization
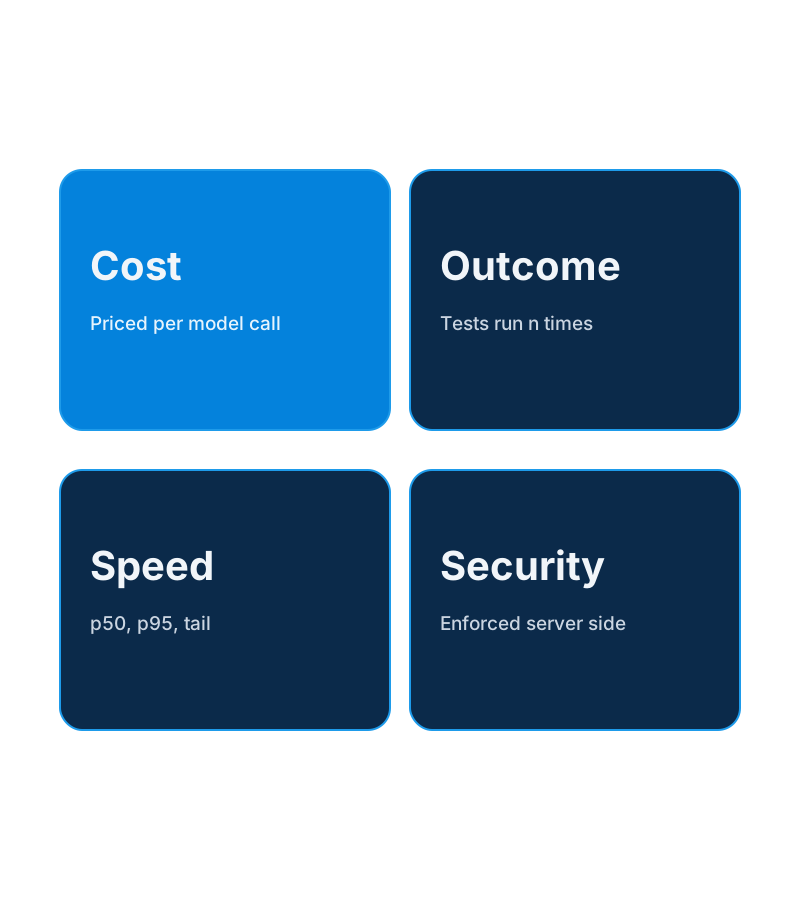
Measure every agent on cost, outcome, speed and security.
Every call is recorded with its time, and every model call with its price. Swap the model per agent, run the same tests on both, and switch when nothing regresses.
Speaker notes
Cost: one ledger, broken down by agent, function, model, provider and user, with test runs separated from real use. Outcome: acceptance tests checked by code (invokesTool, toolParametersContain, respondsWithin) or judged by a model (doesNotHallucinate, satisfiesAssertion); a judged criterion runs 5 times by default and passes on the lower bound of a 95% confidence interval. Experiments run the tests against a changed setup, such as a cheaper model, and report improved, regressed or no difference with cost and speed. Speed: p50, p95 and tail per agent and per connected system, so a slow prompt and a slow system look different. Tests run offline: there is no live traffic split. Telemetry exports to any OpenTelemetry collector.